 NYX
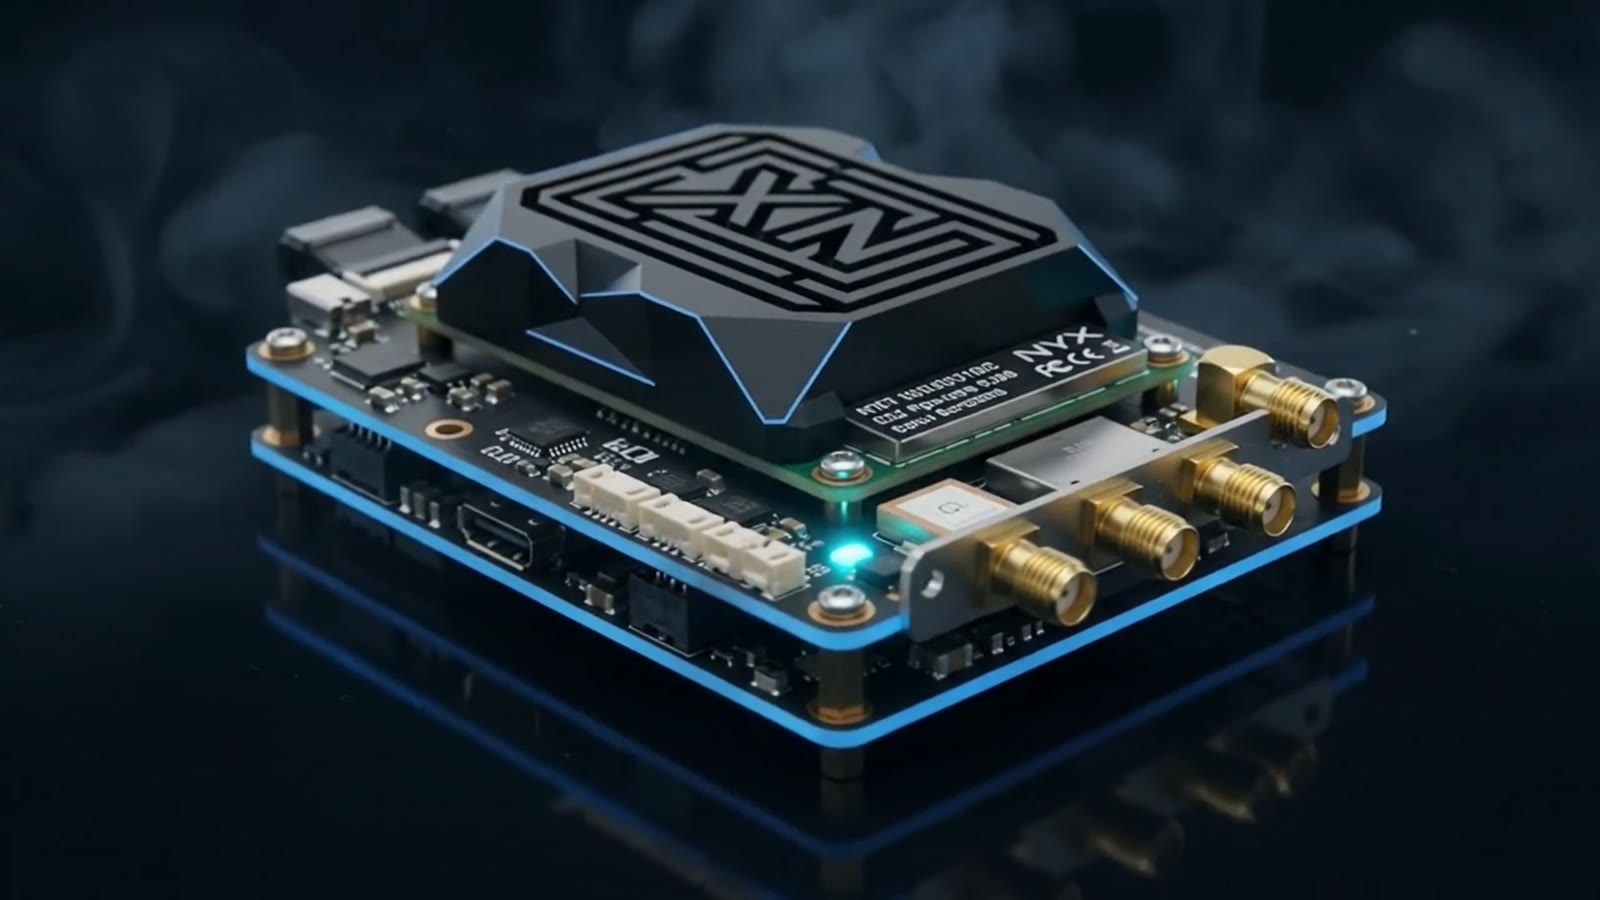
NyxCore
Language models built into FPGA logic, answering from grounded sources where there is no cloud and no link.
What it does
Ternary neural networks are implemented directly in FPGA logic. Each weight takes one of three values, so the datapath adds, subtracts or skips where a general-purpose accelerator would multiply. That cuts power and memory traffic and holds timing steady.
A grounded retrieval harness with constrained decoding keeps the model answering from its sources, so it cannot answer outside them.
The result runs where there is no cloud and no link, on a single card.
Where it runs: A single accelerator card.
Evidence
Language model inference at the edge, up to seven billion parameters measured
A ternary model on a single card, now scaled to as many as seven billion parameters, with grounded retrieval that keeps it answering only from its sources.
Single accelerator card